Pre-Launch Messaging Research Platforms Compared
Choose your research method based on what you're actually trying to decide, not what's cheapest.
When a team decides how to test a message before launch, it usually starts the same way, comparing features and prices across vendors, but that approach has it backwards. A team that runs a live A/B test on day one of copy development is measuring real behavior before it has eliminated the obviously weak drafts. A team that buys a synthetic panel when what it needed was a basic comprehension check with real users is asking a simulation to answer a question only a human can answer. Both mistakes happen because the team skipped the framework and went straight to the shopping list. This guide builds that framework first, then walks through the platforms that fit each stage of it.
The platform category that determines whether pre-launch messaging research is useful
"Message testing" gets used as a single label for three fundamentally different evidence types: simulated-audience directional reads, recruited human-respondent studies, and live behavioral experiments. A simulated audience can tell a team which of five headline drafts is drawing the sharpest objections. A recruited human study can tell a team whether real people actually understand a claim the way the team intends. A live experiment can tell a team whether a message changes what people do with their money, not just what they say in a survey. Treating any one of these as a stand-in for the others produces a specific kind of false positive: a polished chart from a simulated audience gets presented as if it were a representative population estimate, or a live A/B test gets launched before anyone checked whether people even understand the message being tested. The cost of that mistake is not fixed. It scales with the size of the decision riding on the result, so an early headline draft and a final regulated claim should never be validated against the same standard of proof. The sequence that avoids this starts with directional methods to cut the weak variants, moves the strongest two or three into human research once the stakes justify the spend, and only then measures real behavior with a live experiment before scaling media dollars behind it. Speed is a legitimate constraint, and most teams asking for a fast tool are right to ask for one. The right fast tool just depends on which stage of that sequence the team is actually standing in, and that's the question this guide is built to answer.
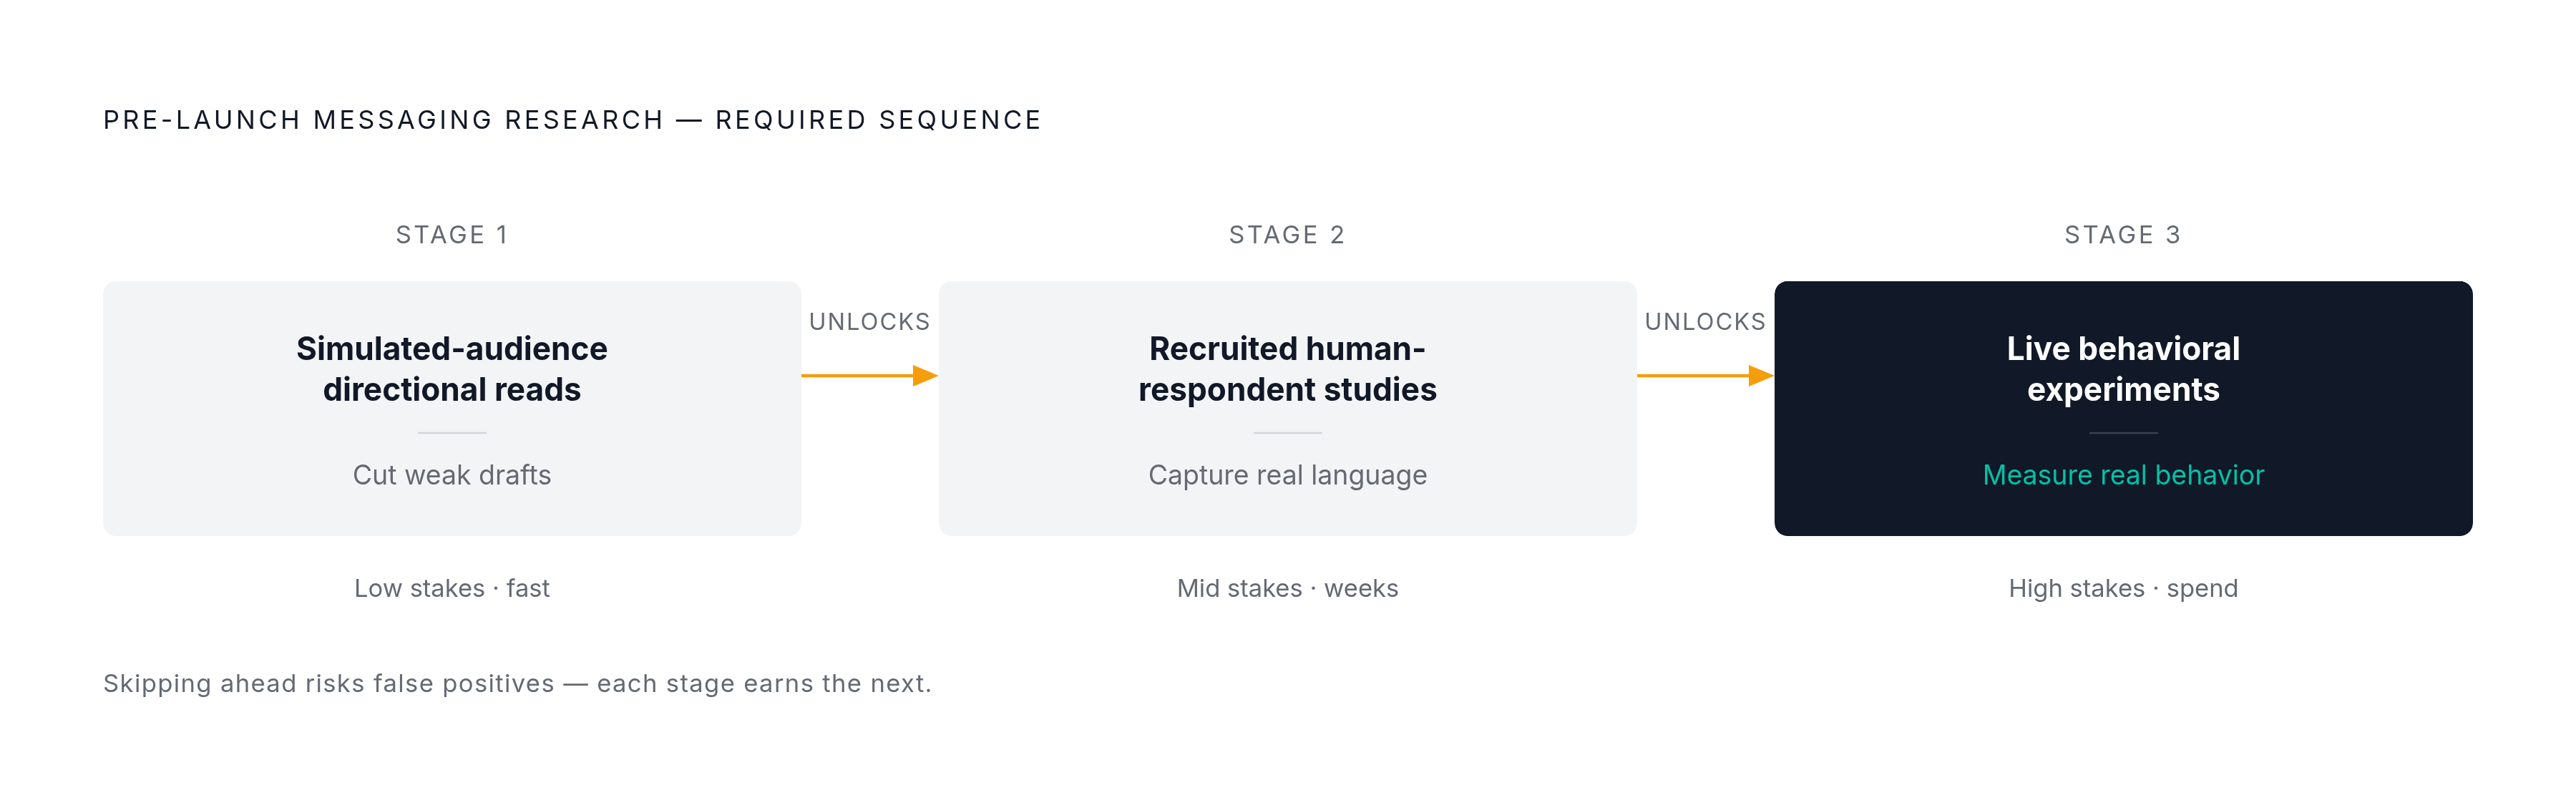
The four questions that define a team's actual evidence requirement before any vendor comparison
Four questions, answered honestly before opening a single vendor's demo, tell a team which platform category it belongs in. The first asks what decision the result will actually change, because research that won't move a decision isn't worth commissioning regardless of how cheap or fast it is. The second asks whose perspective the team actually requires: a directional read from a modeled audience, or the specific words and reasoning of real people. The third asks what stage the team is at, whether it's exploring a wide field of options, selecting among a shortlist, validating a near-final choice, or measuring how a launched message performs in the market. The fourth asks what a false positive would cost: a wrong read on a throwaway tagline costs almost nothing, but a wrong read on a regulated health claim can cost a great deal. Simulated-audience tools fit teams in exploring or selecting mode. Teams validating a near-final message belong in recruited human research. Teams measuring real-world performance belong in a live experiment. This maps onto a risk-tiered framework used in the industry, where ideation, naming, and basic claims sit in low-risk, high-iteration territory that synthetic panels can handle as the primary method, where packaging and product attributes sit in medium-risk territory that synthetic tools support but don't carry alone, and where regulated claims and forecasting demand human testing as the primary method with synthetic work playing a subordinate, supporting role. A team exploring a low-risk decision can read one section of this guide and stop, while a team validating a regulated claim needs all three categories before it's done. One more check applies no matter which platform gets used: comprehension and persuasion are not the same thing, and testing them in the wrong order wastes the whole exercise. A message first has to prove that respondents can accurately restate it unprompted. Only after that's established does it make sense to ask whether the message feels relevant, believable, or likely to drive action.
Simulated-audience platforms: tools built for speed, iteration, and directional diagnosis before human research begins
When ASRV needed to know whether younger buyers responded better to "next-level training gear" or "streetwear built for movement," and whether subscription-based drops would outperform one-off launches, the apparel brand built digital profiles of its core segments, fitness enthusiasts, lifestyle-driven professionals, and trend-conscious Gen Z shoppers, and ran both questions through simulation in hours rather than weeks. That's the kind of work simulated-audience platforms are built for: directional reactions, likely objections, language patterns, and contrasts between segments, delivered fast enough to iterate on a message multiple times before a single human respondent is ever recruited. What these tools do not produce is a representative population estimate, and labeling simulated output as simulated is a basic requirement of evidence hygiene rather than a disclaimer to bury in fine print.
The reason this category works at all now, and didn't a few years ago, comes down to how far large language models have matured. A PyMC Labs pricing study built around a fictional Ford Lumina concept vehicle produced a price elasticity curve that closely matched real-world SUV averages using only synthetic respondents.
Seda sits at the front of this category for teams that need speed and scale without giving up rigor. It combines a verified panel of human respondents across 130+ countries with proprietary synthetic AI agents modeled on entire target markets, and that's why it's one of the few platforms that can run synthetic simulation and recruited human interviews in one workflow. A team can build a behavioral model of its target audience once and then run that same synthetic panel against every future messaging decision, turning a one-time research cost into something closer to a reusable asset. Seda supports interviews, UX tests, and consumer simulations at a scale and speed traditional research firms can't match, and running thousands of simulated interviews before committing to a concept is treated as the normal use case rather than an edge case. That global audience is there right away, not gated behind a recruitment timeline or a vendor negotiation, and it spans 130+ countries with no procurement cycle in between. Its AI interviewers probe and follow up rather than just logging static survey answers, which produces richer diagnostic output; a team that knows it is in "exploring" mode on a low-risk decision can stop reading at the first platform category, while one validating a regulated claim needs to read all three. The platform fits product teams, UX researchers, marketers, and growth leaders running pre-launch messaging, value proposition testing, concept screening, and market entry simulations who need answers measured in hours rather than weeks.
Other platforms occupy this same category with different shapes. Electric Twin builds synthetic crowds for large consumer audiences, was built for The Times, and has raised significant funding; it runs on enterprise pricing and fits enterprise teams that need large-scale audience simulation for consumer brands. Aaru runs multi-agent AI for behavioral foresight, is backed by Accenture Ventures, and also costs enterprise pricing, making it a fit for enterprise teams focused on behavioral prediction at scale. OpinioAI runs AI-moderated synthetic focus groups starting from $99 a month, so smaller teams or agencies trying synthetic methods for the first time can get in without an enterprise budget. Sanctum focuses narrowly on pre-launch feature naming and copy testing against a simulated user base, as a self-service tool built specifically for naming and copy, suiting product marketers who want that focus.
AI-moderated qualitative interview platforms: tools that go beyond directional reads to capture the language and reasoning behind reactions
Once a team moves past directional diagnosis and needs the actual words real people use, not a modeled approximation of them, the next category is AI-moderated qualitative interviews. These platforms add verbatim customer language, probing follow-up that surfaces the reasoning behind a reaction, and contextual nuance that a static survey misses. A follow-up question like compared to what, and what would have felt fair turns a flat read like "the pricing felt steep" into something a landing page can actually use. Listen Labs has run millions of AI-powered customer interviews for companies including Microsoft, Perplexity, and Sweetgreen, a volume that signals this category has moved well past early-adopter territory. This category produces rich explanation and context from smaller samples, but it does not establish market-level demand or a statistically representative population estimate, which is a different job for a different tool.
Koji is a clear example of what a dedicated platform in this category looks like. Interviews start at a low per-interview rate across both text and voice formats; you can start free with a small credit allocation and no card required, pay as you go with no subscription obligation, and volume plans are available if your team runs interviews continuously. It's built so a marketer can launch a full AI-moderated voice or text interview study and come back, within hours, with verbatim customer language, scale ratings, and a publishable insight report. A single study can combine six structured question types, open-ended, scale (NPS or CSAT), single choice, multiple choice, ranking, and yes/no, which lets a team pair qualitative "why" with quantitative scoring in one pass. The AI moderator can be tuned to match a brand's voice, whether that's a friendly DTC tone, a formal B2B register, or a founder-led style, so the conversation feels native to the context it's being run in. Audience sourcing is flexible: a team can import its own customer or prospect list for personalized links, share an anonymous link to encourage candor, or have Koji recruit across 130+ countries at a per-respondent credit quote approved before the study launches. The pricing model only charges for conversations that produce insight, with drop-offs, spam, and low-effort answers excluded from cost, and reports publish as a shareable link rather than requiring a slide deck to be built around them. That combination fits growth marketers, brand marketers, B2B marketers running account-based messaging, DTC founders, and CMOs at startups through mid-market who need verbatim language for campaign concepts, value proposition testing, pricing language, or win/loss interviews.
Two other platforms round out this category with narrower focuses. Quantilope automates more than twelve advanced research methods, including MaxDiff, conjoint analysis, and Van Westendorp price sensitivity, and layers in "Category Twins," its term for always-on synthetic consumers, making it a fit for research teams that want advanced quantitative methods and a synthetic panel in the same platform. Stravito, paired with its Langston MCP server, inserts verified consumer research directly into enterprise AI tools and generates research-grounded buyer personas, which suits enterprise teams that want to put existing verified research to work inside their AI workflows rather than commission new primary studies. This category and simulated-audience platforms aren't mutually exclusive: Seda also supports AI-moderated interviews within its own platform, letting a team move from synthetic exploration into recruited human validation without switching tools or vendors mid-project.
Automated concept and creative testing platforms: tools that score and benchmark messaging before it reaches a live audience
The third category answers a different question than either simulation or interviews do. It's not asking what people say about a message, it's asking how that message scores against a validated norm base and how it compares to alternatives at scale. That distinction matters most for messaging decisions that need a defensible, benchmarked answer before a brand commits significant media spend behind them, so Fortune 500 CPG brands use this category as a standard pre-launch gate, not an exploratory step. This category typically runs on automated test design, AI-scored open-end responses, and benchmarking against large historical test databases, and what matters isn't speed by itself but how well a new concept compares against a record of what has actually worked in that category before. Neuromarketing and emotion-measurement tools extend the same approach into attention and affect: they evaluate emotional reactions, measure viewer attention levels, and link specific creative features to predicted business outcomes at the level of an individual asset.
The strongest outside validation for this category's reliability comes from a BCG conjoint accuracy finding: a synthetic panel predicted real-world consumer choices for a new beverage with 92% accuracy once fine-tuned, and similar accuracy rates have been reported across food and beverage, household goods, and apparel categories. Zappi is the clearest named example of a platform built for this stage. It runs automated ad and concept testing and is used by Fortune 500 CPG and consumer brands for pre-launch creative testing, packaging, innovation screening, and concept iteration, priced on a subscription model that combines a platform fee with research credit bundles. Its AI features include automated test design, AI-scored open-end responses, and benchmarking against a large database of historical tests, which is what lets brand and innovation teams at large consumer goods companies get a defensible, benchmarked answer before a concept moves into full production.
Lined up against the two earlier categories, this one closes the loop a pre-launch sequence depends on. Simulation eliminates the weak variants fast, interviews capture the exact language and reasoning behind how the strongest ones land, and concept testing puts a number on how the finalists stack up against a category's own history before real money follows them into market.
Sources
- The latest AI-powered martech news and releases | MarTech
- Synthetic Consumers in Market Research - A Practical Guide (2026) — PyMC Labs Blog
- Product-Market Fit Testing with Synthetic Consumer Panels
- AI Message Testing Tools in 2026
- Best AI Tools for Marketing Research Teams in 2026: 10 Platforms Ranked
- 10 AI Market Research Tools & How To Use Them
- Synthetic Panels: An AI-powered Solution for Market Research